
Key Takeaways
- vLLM is splitting model execution into hardware-specific ‘flat’ models for frontier NVIDIA GPUs and portable hardware-agnostic layers that keep out-of-tree accelerators viable, shipping behind the USE_HW_AGNOSTIC=1 flag.
- The hardware-agnostic layers land within 3.4% of native CUDA-optimized throughput on H100s across a geometric mean of three recent models, with a DeepSeek V4 pull request already under review.
- Four design constraints — compilable, extensible, isolated, and portable — preserve torch.compile and CustomOp support that Intel XPU, IBM Spyre, and other non-NVIDIA fleets depend on.
Table of Contents
vLLM’s Architecture Splits Into Two Paths
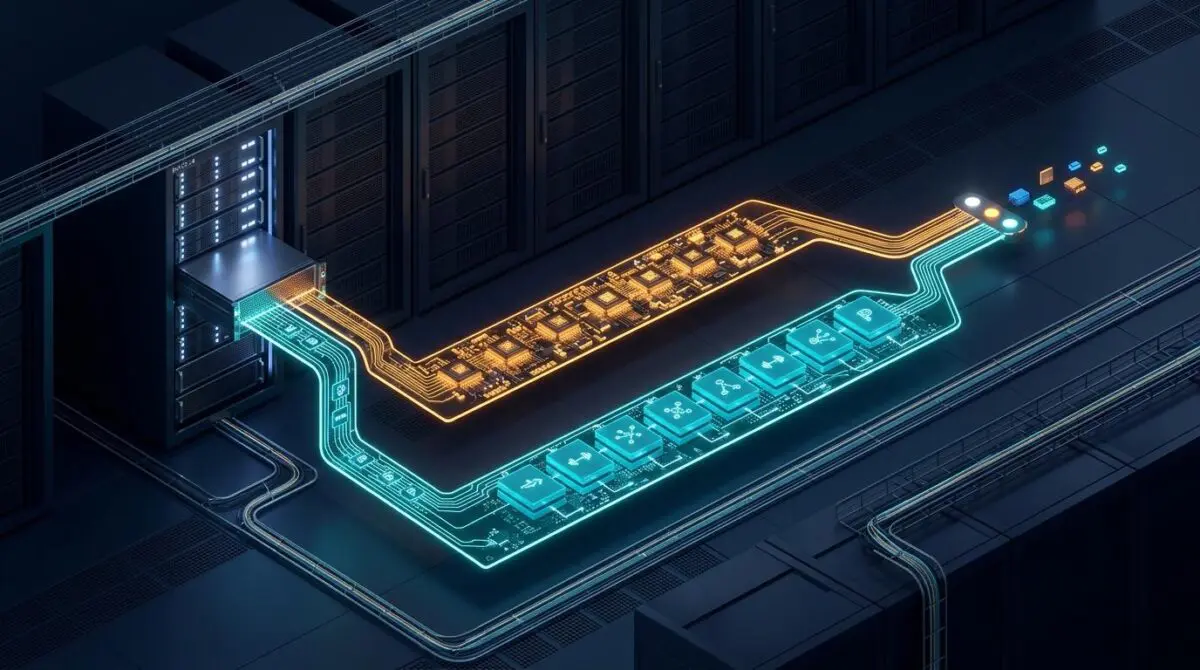
The vLLM project is splitting its model execution strategy in two: one path optimized for frontier NVIDIA GPUs through hardware-specific ‘flat’ models, and a newly introduced set of hardware-agnostic layers designed to keep out-of-tree accelerators and older GPUs viable. PyTorch’s engineering blog broke the news on September 22, 2026, reporting that the portable path already lands in the main branch behind the USE_HW_AGNOSTIC=1 flag.
On NVIDIA H100 GPUs, those hardware-agnostic layers deliver total token throughput within 3.4% of native CUDA-optimized implementations across a geometric mean of three recent models. That gap is narrow enough to matter for portability-focused deployments, while still conceding frontier speed to the flat model path.
Inside the Hardware-Agnostic Layer Contract
vLLM currently serves model definitions through three routes: new flat models under vllm/models, legacy models under vllm/model_executor/models, and the Transformers modeling backend. Despite these separate locations, most implementations converge on shared layers for attention, mixture-of-experts blocks, linear projections, norms, and activations.
As detailed in PyTorch’s engineering blog, flat models changed that calculus. To extract maximum Blackwell and rack-scale performance, they use custom fusions and model-specific kernels instead of relying on fullgraph torch.compile.
The trade-off is explicit. Moving flat models forward requires breaking torch.compile compatibility and removing CustomOp extensibility, which out-of-tree plugins such as IBM Spyre depend on to trace and lower model graphs.
The hardware-agnostic layer initiative responds with four design constraints:
- Compilable — model definitions remain fullgraph torch compilable for accelerators that require compile for performance.
- Extensible — CustomOp and PluggableLayer mechanisms stay intact so out-of-tree plugins can override implementations when necessary.
- Isolated — portable layers and ops are separated from hardware-specific paths so both workstreams can move quickly.
- Portable — implementations use native PyTorch or portable DSLs such as Triton and Helion.
For the Transformers backend, the rewiring process now targets the new hw_agnostic path instead of the legacy layers. A limited set of layers has already landed, with validation through the Spyre out-of-tree plugin for Gemma 4, Qwen3, and Granite 4.2.
Plans call for a parallel hardware-agnostic model.py for each flat model. Shared layers will live in hw_agnostic, while model-specific kernels remain local but follow the same four principles.
A hardware-agnostic DeepSeek V4 pull request is already under review.
Portable Throughput Meets XPU and Competitive Pressure
The strategic value of the split becomes clearer when placed against the broader inference engine market. Directional benchmarks from an infrastructure provider’s serving guide put SGLang roughly 29 percent faster than vLLM in multi-turn scenarios, while TensorRT-LLM leads raw NVIDIA throughput but remains hardware-specific.
That positions vLLM’s competitive moat less around raw H100 speed and more around deployment breadth.
Intel’s official ai-containers documentation for vLLM 0.10.2 reinforces that breadth. It lists validation on Intel Arc Pro B-Series GPUs and support for chunked prefill, FP8 W8A16 weight-only dynamic quantization, MoE, pooling, and pipeline parallelism across Intel XPUs.
The Intel notes also claim up to 1.6x throughput improvements from FP8 quantization and attention decoding gains above 10 percent on more than ten models. Those are vendor-published figures rather than independent benchmark reports, but they signal active hardening outside NVIDIA.
That ecosystem reality mirrors the original design argument. Without portable, compilable layers, out-of-tree accelerators would need to maintain their own model definitions and layer implementations, multiplying pull-request burden across Transformers, vLLM, and every plugin.
The H100 result within 3.4 percent of native throughput suggests portability no longer automatically means a large performance penalty. For teams running mixed fleets or non-NVIDIA silicon, that narrow delta is the more important benchmark than absolute frontier speed.
Inference Fleets Need a Portable Baseline
The vLLM split formalizes what inference teams already know: frontier speed and hardware portability are no longer the same engineering problem. The hardware-agnostic layers give mixed-fleet deployments a credible baseline without freezing the performance work on Blackwell and beyond.
For teams publishing technical authority around AI infrastructure shifts like this one, Andres SEO Expert’s programmatic SEO and AI automation practice turns niche insight into compounding visibility — start the conversation here.
Frequently Asked Questions
What is vLLM’s hardware-agnostic layer initiative?
It is a portable model execution path in vLLM that keeps out-of-tree accelerators and older GPUs viable. It lands behind the USE_HW_AGNOSTIC=1 flag and follows four constraints: compilable, extensible, isolated, and portable.
How close is vLLM’s hardware-agnostic path to native CUDA on H100 GPUs?
On NVIDIA H100 GPUs, the hardware-agnostic layers deliver total token throughput within 3.4 percent of native CUDA-optimized implementations across a geometric mean of three recent models.
What are the four design constraints of vLLM’s hardware-agnostic layers?
The layers must be compilable for fullgraph torch.compile, extensible through CustomOp and PluggableLayer, isolated from hardware-specific paths, and portable using native PyTorch or portable DSLs such as Triton and Helion.
Why did vLLM split its model execution into flat models and hardware-agnostic layers?
Flat models extract maximum Blackwell and rack-scale performance using custom fusions and model-specific kernels, but they break torch.compile compatibility and remove CustomOp extensibility. The hardware-agnostic layers preserve portability and plugin support for out-of-tree accelerators.
Which models and plugins validate vLLM’s hardware-agnostic path?
A limited set of layers has been validated through the IBM Spyre out-of-tree plugin for Gemma 4, Qwen3, and Granite 4.2. A hardware-agnostic DeepSeek V4 pull request is already under review.
How does vLLM’s portable path compare with SGLang and TensorRT-LLM?
Directional benchmarks put SGLang roughly 29 percent faster than vLLM in multi-turn scenarios, while TensorRT-LLM leads raw NVIDIA throughput but remains hardware-specific. vLLM’s moat is deployment breadth rather than raw H100 speed.
What does Intel’s vLLM 0.10.2 XPU support show about portable inference?
Intel’s ai-containers documentation lists validation on Intel Arc Pro B-Series GPUs and support for chunked prefill, FP8 W8A16 weight-only dynamic quantization, MoE, pooling, and pipeline parallelism. Intel also claims up to 1.6x throughput improvements from FP8 quantization and attention decoding gains above 10 percent on more than ten models, though these are vendor-published figures.