
Key Takeaways
- LiquidAI’s 280M DSpark drafter boosts LFM2.5-VL-3B decoding up to 3.13x on an M5 Max and 2.66x on an H100 for just 8.9% more parameters.
- Speculative decoding stays exact: the frozen target verifies every proposed token, so greedy output matches the base model with no quality loss.
- Rivals such as GLANCE warn that compact drafters can lose visual grounding, and decode-only gains remain capped by prefill and vision encoding costs.
Table of Contents
On-Device Vision Decode Just Got a 3x Turbo
LiquidAI has released an experimental draft model that accelerates its LFM2.5-VL-3B vision-language model by up to 3.13x during token decoding on Apple silicon.
Hugging Face reports the 280-million-parameter add-on, called LFM2.5-VL-DSpark, trades an 8.9% parameter increase for faster inference without altering output quality.
The drafter ships with day-one integrations for llama.cpp, MLX-VLM, and SGLang.
On an M5 Max, decode throughput improves by 2.30x to 3.13x, with end-to-end latency gains up to 2.62x.
On an H100, decode gains reach 2.66x, while end-to-end improvements top out at 2.27x.
The release, detailed on the Hugging Face blog, lands on September 24, 2026, at a moment when edge multimodal workloads are moving from text-only assistants to real-time image and chart understanding.
Inside the DSpark Draft Model
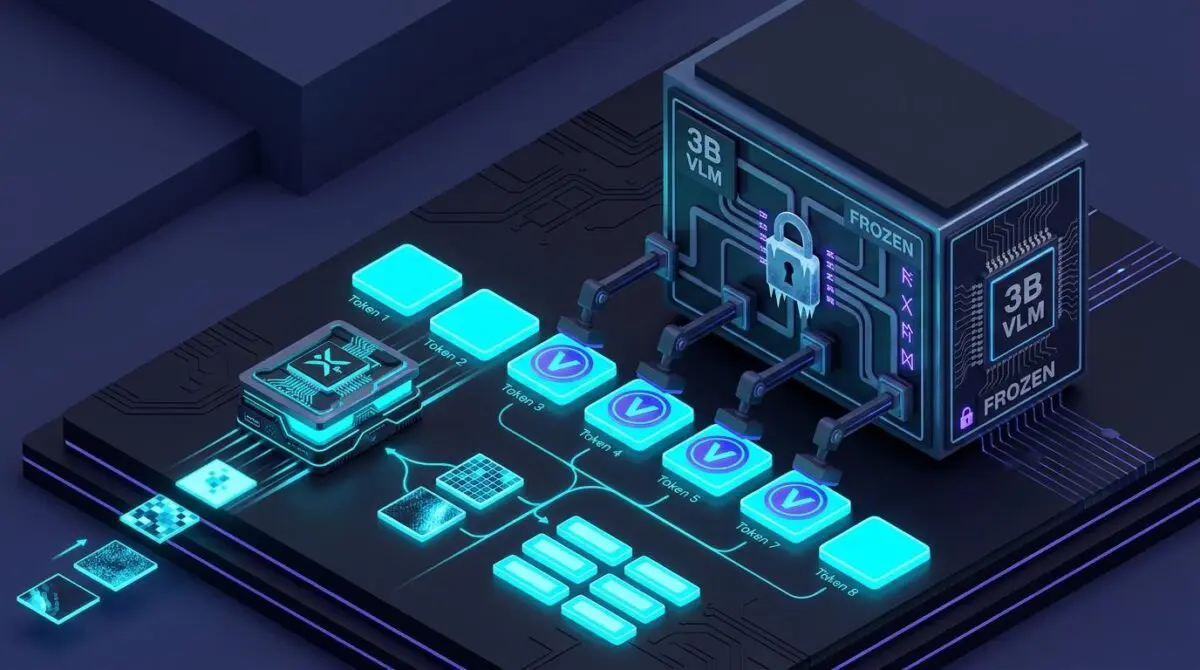
The DSpark setup reads hidden states from a fixed set of layers inside the frozen LFM2.5-VL-3B target.
Those states condition a lightweight network that proposes a block of candidate tokens for the target model to verify.
Before those tapped layers, visual patches and word tokens are mapped into a single shared embedding space.
As a result, the vision drafter sees the same vector dimension for any input type.
The draft network itself is an attention-only decoder stack with four layers and a training block size of nine.
LiquidAI settled on that shape after ablating three, four, and five layers.
Ten epochs on a vision-language SFT mixture produced acceptance gains that hit diminishing returns.
At inference, the recommended block size is eight or nine, depending on the deployment hardware.
- Decoder stack: 193.0M parameters
- Hidden-state projection: 21.0M parameters
- Markov head: 65.5M parameters
- Norms and confidence head: 6.4k parameters
- Total: 279.5M parameters
The combined overhead sits near 8.9% on top of the 3B target model.
One property separates this approach from aggressive compression schemes.
Speculative decoding is exact: the target verifies every proposed token, so greedy output equals the target alone.
That means the speedup comes from cutting sequential decode steps, not from accepting noisier approximations.
On Apple silicon, results vary by task.
MLX on an M5 Max posts decode gains of 2.30x to 3.13x, with end-to-end latency improvements between 1.56x and 2.62x.
The llama.cpp path on an M3 Ultra shows decoding gains from 1.57x to 2.14x and end-to-end improvements of 1.30x to 1.77x.
The evaluations use six vision-centric tasks from the MMSpec benchmark, covering general and text VQA, captioning, chart reasoning, complex reasoning, and multi-turn conversation.
For SGLang, the integration relies on a build with DSpark support for LFM2 targets, tracked in PR #40651.
The llama.cpp and MLX-VLM paths require their own respective builds under PR #29339 and PR #2280.
Where Speculative Decoding Stalls — and Rivals Push Back
On paper, a 3x decoding improvement looks transformative.
In vision-language models, a substantial share of end-to-end latency comes from prefill and vision encoding, not token generation.
Speculative decoding accelerates only the decode phase, so Amdahl’s law caps the real-world gain on slower edge processors.
NVIDIA’s speculative decoding guidance makes the same trade-off explicit.
Draft models help most when a deployed GPU has spare compute at low-to-moderate concurrency.
Under saturated load, the extra work from a separate drafter can reduce throughput rather than improve it.
A recent arXiv preprint describing the GLANCE architecture pushes that critique further for VLM-specific drafters.
It argues that small autoregressive drafters cannot afford full image tokens at every step, so visual information gets compressed or hidden.
The result is weak speculation exactly where images make text easier to predict: charts, documents, and grounded questions.
GLANCE instead uses a block-diffusion head that reads the frozen target’s already-fused vision-language hidden states and fills an entire block in one forward pass.
In SGLang 0.5.6, the GLANCE paper reports a 2.93x decode speedup on ChartQA against autoregression.
Against the production EAGLE3-VL head, GLANCE is 7.6% faster on InfographicVQA and 6.0% faster on ChartQA, but 16.2% slower on captioning and 19.1% slower on TextVQA.
Accepted block length tracks grounding: 4.62 on ChartQA, 3.93 on DocVQA, and 2.91 on captioning.
LiquidAI’s DSpark is not the same architecture as EAGLE3-VL.
Its four-layer attention-only draft model and shared multimodal hidden-state projection occupy a different design point.
Still, the GLANCE result raises a pointed question for any compact drafter: how much visual grounding survives when the draft model must propose tokens from a constrained hidden-state view?
The broader ecosystem is moving in the same direction.
OpenVINO’s 2026.4 release added Qwen3-VL-4B support with Eagle 3 on CPUs and GPUs, plus multi-token prediction for Gemma 4 and Qwen 3.5.
Those performance numbers are vendor-supplied, but the direction is clear: edge multimodal acceleration is becoming a default feature.
Edge Vision Models Cross the Latency Threshold
The shipping of a 280M drafter for a 3B vision model turns speculative decoding into a day-one edge feature rather than a post-deployment fix. For teams building AI-driven content pipelines that need to scale without sacrificing performance, programmatic SEO and AI automation is how Andres SEO Expert approaches that challenge — contact us.
Frequently Asked Questions
What is LFM2.5-VL-DSpark?
LFM2.5-VL-DSpark is a 279.5M-parameter experimental draft model from LiquidAI that accelerates the LFM2.5-VL-3B vision-language model by up to 3.13x during token decoding on Apple silicon and up to 2.66x on H100.
How does DSpark speculative decoding work?
DSpark reads hidden states from fixed layers in the frozen LFM2.5-VL-3B target. A lightweight four-layer attention-only decoder proposes a block of candidate tokens, and the target model verifies every token before accepting it.
Does DSpark change the output quality of the vision-language model?
No. Speculative decoding is exact because the target verifies every proposed token. Greedy output equals the target model alone, so the speedup comes from fewer sequential decode steps rather than from approximate or noisier outputs.
How much faster is DSpark on Apple silicon and NVIDIA H100?
On an M5 Max with MLX, decode gains are 2.30x to 3.13x and end-to-end latency improves 1.56x to 2.62x. On llama.cpp with M3 Ultra, decode gains are 1.57x to 2.14x. On H100, decode gains reach 2.66x and end-to-end improvements top out at 2.27x.
What are the limitations of speculative decoding for vision-language models?
Speculative decoding only accelerates the decode phase, while prefill and vision encoding can dominate end-to-end latency. Under saturated GPU load, a separate drafter may reduce throughput. Small autoregressive drafters may also lose visual grounding on charts, documents, and grounded questions.
How does DSpark compare with GLANCE and EAGLE3-VL?
DSpark is not the same architecture as EAGLE3-VL. GLANCE uses a block-diffusion head and reports a 2.93x decode speedup on ChartQA, beating EAGLE3-VL by 7.6% on InfographicVQA and 6.0% on ChartQA, but trailing it by 16.2% on captioning and 19.1% on TextVQA. DSpark instead uses a four-layer attention-only draft model with shared multimodal hidden-state projection.
What integrations and hardware support DSpark?
DSpark ships with day-one integrations for llama.cpp, MLX-VLM, and SGLang. The SGLang path requires a build with DSpark support for LFM2 targets in PR #40651, while llama.cpp and MLX-VLM require builds under PR #29339 and PR #2280.