
Key Takeaways
- Identical patches pass 69.4% of checks without live serving but only 45.9% with it, so roughly one in three passing patches breaks on a real server.
- Multi-domain tasks fall 21.3 percentage points versus single-domain tasks (69.0% to 47.7%), and every tested model declined.
- Cost does not track capability: four models tied at 64% pass@1 range from $0.95 to $7.24 per task, and native agent harnesses scored below mini-swe-agent.
Table of Contents
The 45 Percent Cliff: When a Passing Patch Fails the Real Server
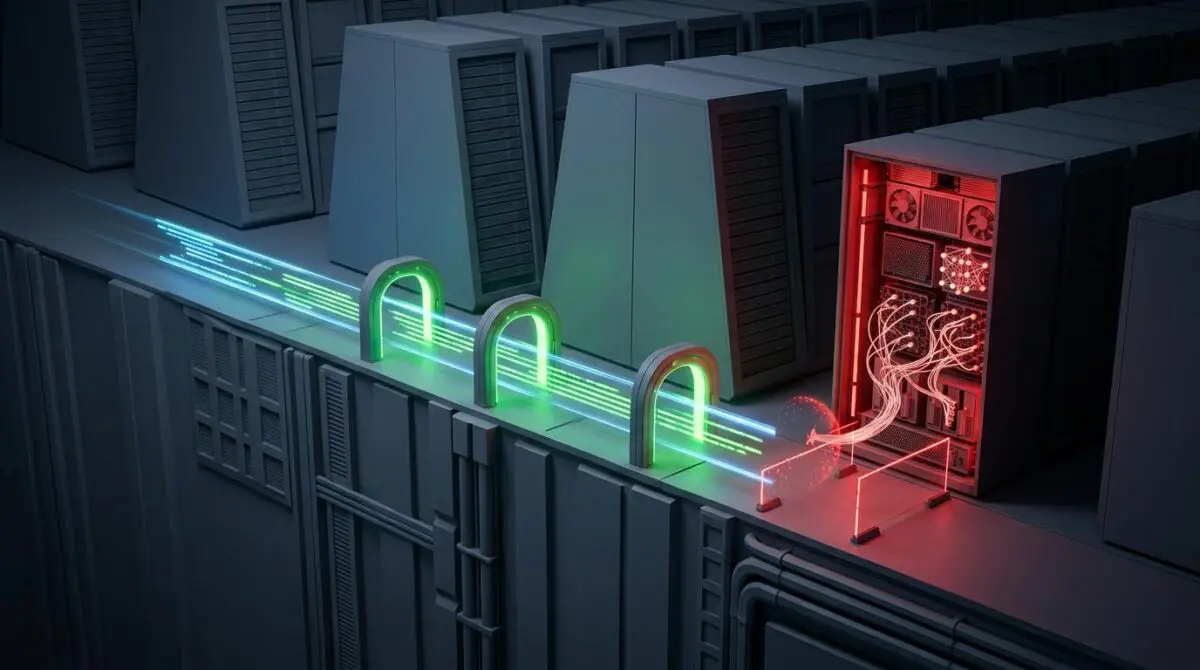
Published on the NVIDIA developer blog, the SWE-Serve benchmark reveals a hard failure mode in AI coding agents: a patch can pass every local test and still break the moment a real model loads into live serving.
The gap is not marginal. Across 19 tasks that start a live server, identical patches passed 69.4 percent of the time when live-serving checks were excluded, but only 45.9 percent under the complete verifier.
That means roughly one in three patches cleared all other checks and then failed when exposed to actual model loading, request handling, and response correctness.
As detailed on the NVIDIA developer blog, SWE-Serve turns 83 merged pull requests into 53 executable inference-engineering tasks, developed with input from the SGLang team.
The benchmark focuses on the full path from model enablement and decoding to caching, scheduling, serving APIs, and distributed execution.
Inside SWE-Serve: 53 Tasks Rebuilt From Real Serving Software
Every SWE-Serve task starts from a containerized SGLang checkout before the target change. An agent receives an instruction and must submit a patch that satisfies a hidden verifier on declared hardware.
The reference solutions are substantial. A median patch modifies 553 lines across seven files, and a typical verifier carries seven tests for new behavior plus 10 regression tests.
Tasks are organized across six engineering families:
- Speculative and advanced decoding: 14 tasks
- Model and backend enablement: 12 tasks
- Kernels, quantization, and performance: 8 tasks
- Serving APIs and runtime correctness: 8 tasks
- Caching and runtime state: 7 tasks
- Distributed execution and scheduling: 4 tasks
Twelve tasks run on CPU, while 41 use a single NVIDIA H100. The first release does not evaluate other inference engines, multi-GPU execution, or multi-node serving.
Nineteen tasks directly test the live serving path. Across the 276 live-serving checks in those tasks, 242 were sourced or adapted from SGLang.
The Gemma 4 MoE task illustrates the failure pattern. Sixteen of 33 patches passed every other check but failed at least one live-serving test.
Those failures covered model loading, expert routing, text and image serving, and batched generation with correct ordering and log probabilities.
Another example is the Qwen3.5 task, where an agent must add serving support for both dense and mixture-of-experts models on one H100. The verifier checks model registration, weight loading, image and video inputs, OpenAI-compatible requests, native batched generation, and execution through routed experts.
SWE-Serve also splits the request-to-output path into four runtime domains: request handling and I/O, scheduling and request lifecycle, model execution, and KV-cache and runtime-resource management.
Single-domain tasks reached a 69.0 percent pass rate across the best model settings. Multi-domain tasks fell to 47.7 percent, a 21.3 percentage-point drop.
Every tested model showed the same direction of decline.
How the Benchmark Was Qualified
The team screened 786 potential task sources, built 156 executable candidates, and admitted 53. Each admitted task required the unmodified repository to fail the new behavior while passing regression tests, and a reference patch had to pass the complete verifier.
Evaluation was closed-book. Public web access and upstream source repositories were blocked, while Hugging Face remained available for model weights.
Across 1,749 audited trials, 196 prohibited retrieval attempts were blocked, and none succeeded.
Model Spread, Costs, and the Economic Reality of Inference Agents
Eleven models were evaluated under closed-book conditions with mini-swe-agent, a minimal software-engineering agent that relies only on Bash.
The best-scoring configuration for each model ranges from 34.6 percent to 75.5 percent pass@1. The leaders are Claude Opus 5 and GPT-5.6 Sol, both at 75 percent, though with different cost and runtime profiles.
Cost does not track performance cleanly. Among four models tied at 64 percent, mean cost per task ranges from $0.95 to $7.24, and mean wall time spans 25.5 to 99.9 minutes.
- Claude Opus 5: 75% pass@1, $17.40 per task, 57.5 minutes
- GPT-5.6 Sol: 75% pass@1, $12.26 per task, 29.5 minutes
- Claude Sonnet 5: 64% pass@1, $6.61 per task, 40.6 minutes
- Kimi K3: 64% pass@1, $7.24 per task, 99.9 minutes
- GPT-5.6 Luna: 64% pass@1, $0.95 per task, 28.9 minutes
- GPT-5.6 Terra: 64% pass@1, $5.06 per task, 25.5 minutes
- DeepSeek V4 Flash: 55% pass@1, $0.69 per task, 36.4 minutes
A cheaper model may need more retries to reach a solved state, erasing the advantage of a lower per-task sticker price.
Native agent harnesses did not improve the two leaders. GPT-5.6 Sol scored 73.6 percent in Codex and Claude Opus 5 scored 69.8 percent in Claude Code, both below their mini-swe-agent results.
The finding suggests that agent scaffolding, not just raw model capability, is a limiting factor on inference-serving tasks.
No model led all six engineering families. Models with the same overall score showed different strengths across decoding, caching, scheduling, and API correctness.
For enterprises that deploy AI agents against production inference systems, SWE-Serve makes a critical distinction visible: passing local unit tests is not a valid release signal.
Live-serving verification catches failures in model loading, expert routing, batch ordering, and log probabilities that static tests cannot see.
The 21.3-point multi-domain gap also indicates that agents struggle most with cross-cutting runtime reasoning. This is precisely where production serving systems fail.
One important boundary exists. A SWE-Serve pass only means the patch satisfied the benchmark verifier. It does not mean the patch is deployable, ready to merge, or endorsed by SGLang maintainers.
What the Serving Gap Means for AI Engineering Teams
SWE-Serve turns a previously invisible failure mode into a measurable engineering signal. Teams building AI coding agents for inference-serving work now have a concrete benchmark to expose the distance between a passing patch and a working server.
For teams building agent evaluation pipelines that need to scale, the programmatic SEO and AI automation practice at Andres SEO Expert is built for this — contact us.
Frequently Asked Questions
What is SWE-Serve and what does it measure?
SWE-Serve is a benchmark from NVIDIA that turns 83 merged pull requests into 53 executable inference-engineering tasks, developed with input from the SGLang team. It measures whether an AI coding agent can produce a patch that works in real serving software, covering model enablement, decoding, caching, scheduling, serving APIs, and distributed execution.
What is the 45 percent cliff in AI coding agents?
The 45 percent cliff refers to a gap where identical patches passed 69.4 percent of the time when live-serving checks were excluded, but only 45.9 percent under the complete verifier. That means about one in three patches passed other checks and then failed during actual model loading, request handling, or response correctness.
Why can an AI coding agent patch pass local tests but fail live serving?
Local tests often miss runtime behavior that only appears in a live server. SWE-Serve catches failures in model loading, expert routing, batch ordering, text and image serving, and log probabilities that static checks cannot see.
Which inference-serving tasks are hardest for AI agents on SWE-Serve?
Multi-domain tasks are hardest. Single-domain tasks reached a 69.0 percent pass rate, while multi-domain tasks fell to 47.7 percent, a 21.3 percentage-point drop. The hardest work spans request handling, scheduling, model execution, and KV-cache or runtime-resource management.
How do AI models perform on SWE-Serve, and does lower cost mean better results?
Eleven models were evaluated under closed-book conditions. Best configurations range from 34.6 percent to 75.5 percent pass@1. Claude Opus 5 and GPT-5.6 Sol both reached 75 percent, but cost and runtime varied widely; among four models tied at 64 percent, mean cost per task ranged from $0.95 to $7.24. A cheaper model may need more retries, erasing the lower sticker price.
What does the multi-domain gap reveal about production inference systems?
The multi-domain gap shows agents struggle with cross-cutting runtime reasoning, which is exactly where production serving systems tend to fail. Live-serving verification exposes model loading, expert routing, batch ordering, and log-probability issues that local unit tests cannot detect.
What are the limits of passing SWE-Serve?
A SWE-Serve pass only means the patch satisfied the benchmark verifier. It does not mean the patch is deployable, ready to merge, or endorsed by SGLang maintainers. The first release also does not evaluate other inference engines, multi-GPU execution, or multi-node serving.